TL;DR
- Best overall web search API for AI: Firecrawl - web data APIs built for AI agents: Search returns fresh, ranked results with query-relevant excerpts by default (optional full-page fetch in the same call); Scrape, Parse, and Interact handle the rest of the Find → Extract → Clean → Use workflow
- Best for semantic/research search: Exa - neural search trained on link prediction, ideal for RAG and AI agents
- Best for AI search and research workflows: Firecrawl - Research and Developer indexes on one API, token-efficient by default, plus Firecrawl Alexandria, which returns official data providers and licensed publishers as tools in the same search call. Tavily is a solid alternative for source-first discovery with LangChain/LlamaIndex
- Best for developer and code queries: Firecrawl Developer Index - 70M+ READMEs, GitHub issues, PRs, and docs refreshed daily, so a coding agent gets the exact PR that fixed a bug instead of a generic web result
- Best for evidence-backed research agents: Parallel AI - multi-agent retrieval with provenance on every result. Firecrawl is a strong alternative, pairing citable, freshness-monitored sources with optional full-page fetch for verification
- Best traditional SERP API: SerpAPI - 40+ engines, enterprise-grade reliability
- Best budget SERP option: Serper - affordable Google search access
- Best privacy-focused: Brave Search API - independent index, no tracking, $5/1k queries
The web search API market has been changing dramatically with AI applications driving demand for smarter search capabilities. With Microsoft's decision to retire Bing Search APIs in August 2025, developers are evaluating web search API alternatives and discovering new platforms built specifically for AI workflows.
Our web search API comparison examines both traditional SERP APIs and AI-native search engines that power modern applications. Whether you need a search API for RAG systems, semantic search for AI agents, or reliable data extraction for business intelligence, choosing the right platform affects performance, functionality, and costs.
This guide covers the best web search APIs for developers in 2026, including detailed analysis of pricing, capabilities, and ideal use cases. We'll compare everything from enterprise-grade SerpAPI alternatives to specialized platforms like Firecrawl search, Exa, and Tavily that target specific AI workflows. By the end, we hope you find the best web search API for you and your applications.
What is a Web Search API?
A web search API provides programmatic access to search engine results through HTTP requests, returning structured data in JSON or other machine-readable formats instead of visual web interfaces that we use for day-to-day web browsing. For a developer's walkthrough of what a web search API is and how to call one, see the dedicated guide.
What are web search APIs used for?
- AI and machine learning applications consume search results to train models, power chatbots, or enable retrieval-augmented generation systems with clean, structured data that LLMs process efficiently
- Business intelligence tools use search APIs to monitor brand mentions, track competitor content, or analyze market trends across thousands of queries daily
- SEO and marketing platforms automate rank tracking, keyword research, and content gap analysis by querying search engines programmatically
- Research applications gather data from academic sources, news sites, or industry publications at scale
For the sake of this blog, we consider the web search API market as divided into two distinct categories: AI and traditional.
AI-native search APIs like Firecrawl, Exa, and Tavily use neural networks, semantic understanding, or integrated content extraction to deliver information specifically formatted for LLM consumption and AI workflows. These platforms understand context and meaning beyond simple keyword matching. You'll want to use them for RAG systems, AI agents, and applications requiring semantic search capabilities. For multi-step agent workflows that combine live web retrieval with iterative reasoning, see the guide on agentic search for architecture patterns and real-world implementation examples. For a side-by-side feature comparison of the top options, see the guide to best search tools for AI agents.
Traditional SERP APIs including SerpAPI, ScrapingDog, Serper, and Brave focus on extracting and formatting search engine results from established platforms like Google and Bing (or in the case of Brave, using their own index). These services provide familiar search results for applications that need structured access to traditional search engine data that aren't focused on advanced AI capabilities.
If cost is where you're starting, our roundup of the best free web search APIs covers which providers give away a usable free tier and where each one runs out.
A Comparison of Web Search APIs
| Feature | Firecrawl | Exa | Tavily | Parallel AI | SerpAPI | ScrapingDog | Serper | Brave |
|---|---|---|---|---|---|---|---|---|
| Pricing | $16/mo billed annually (5K credits); free tier 1K/mo | $1.50/1k searches | $8/1k PAYG basic search | Pay per query (not listed) | $75+/5k searches | $0.29-1.00/1k | $0.30-1.00/1k | $5/1k queries |
| Free Tier | Yes | 1,000/month | 1,000/month | None | 250/month | 1,000 credits | None | None |
| Output Formats | JSON, Markdown, HTML, Screenshots | JSON, Structured Data | JSON, Citations | JSON with provenance | JSON, Rich Metadata | JSON | JSON | JSON |
| Content Extraction | Full page + custom schemas | Page summaries | Key content extraction | Evidence-backed sourced results | Metadata only | Metadata only | Metadata only | Metadata only |
| AI Integration | Native LLM optimization | Neural semantic search | Citation-ready responses | Multi-agent evidence-based | Structured parsing only | Basic JSON output | Basic JSON output | Basic JSON output |
| Search Approach | AI + Traditional | Neural networks | Source-first discovery | Multi-agent agentic research | Multi-engine SERP | Google SERP | Google SERP | Independent index |
| Integrated Search + Scrape | Yes (single operation) | No | include_raw_content on /search, plus /extract | Task API (multi-step) | No | No | No | No |
| Data providers in search | Yes (Firecrawl Alexandria: 90+ providers and 3 indexes via sources) | No | No | No | No | No | No | No |
| LangChain Support | Yes | Yes | Yes | Limited | Yes | Limited | Yes | Yes |
AI-Native Search APIs
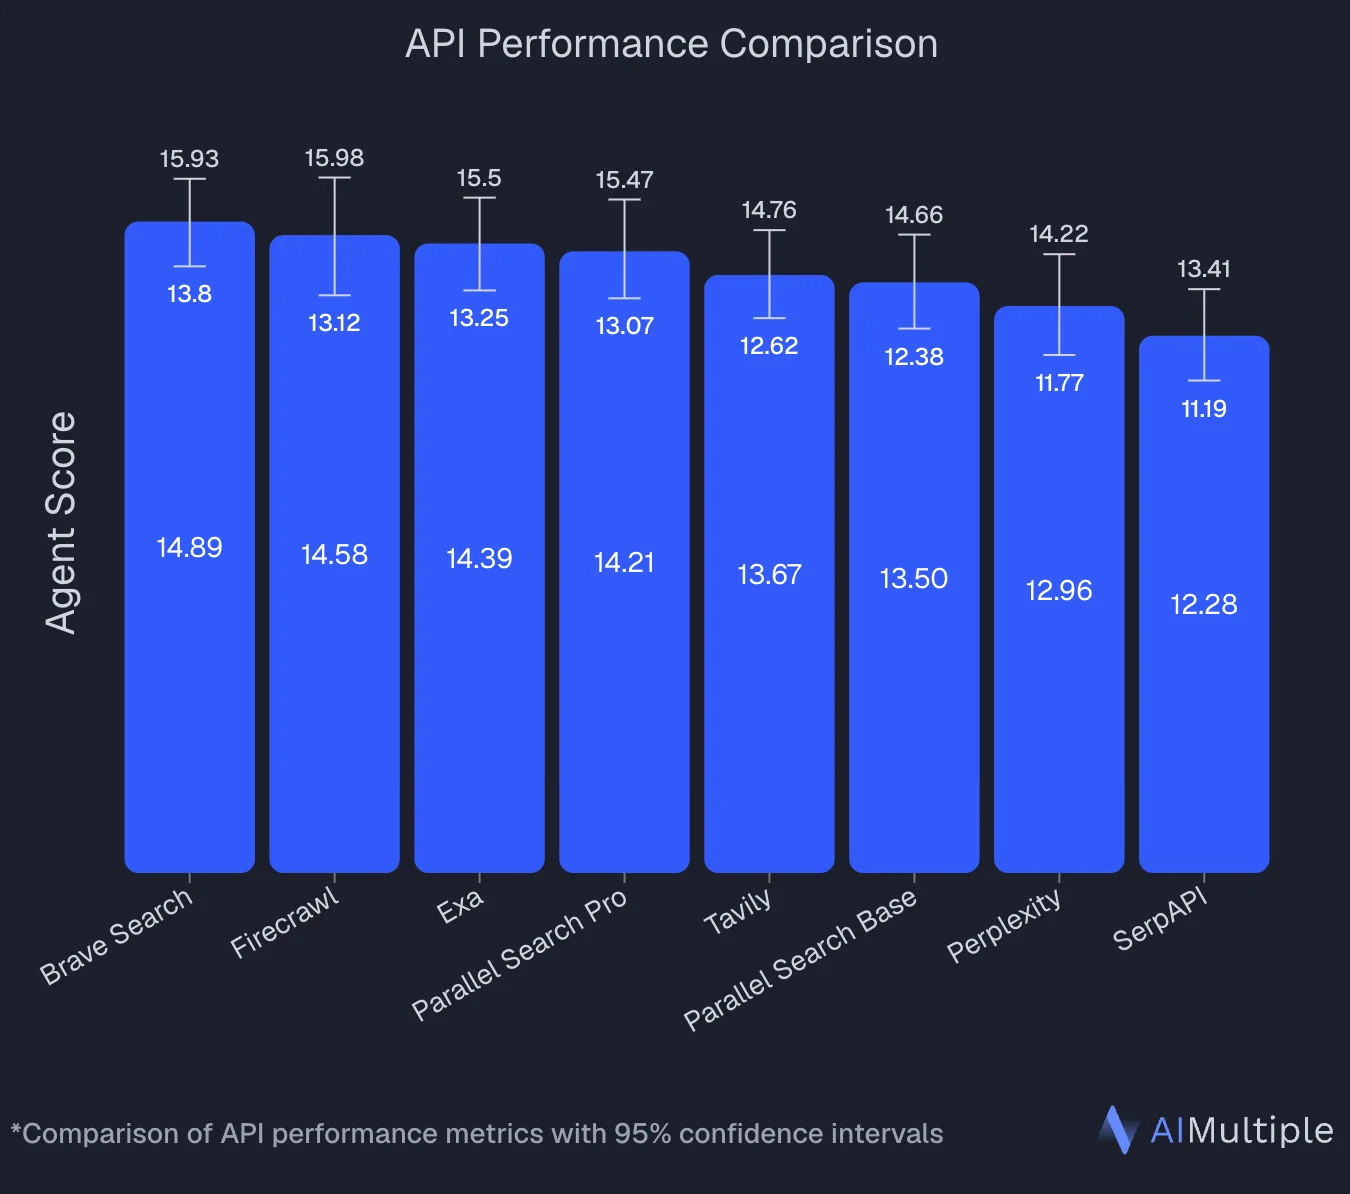
An independent benchmark by AIMultiple tested 8 search APIs on 100 real AI/LLM queries. Firecrawl ranked second overall with an Agent Score of 14.58, statistically tied with Brave Search at the top (14.89), and posted the highest mean relevance score in the run (4.30/5).
It led the field on deep content retrieval, the tasks where full-page context is what decides whether the answer is right.
Web data API built for AI agents
Best for: AI agents that need a standalone search API returning fresh, clean, ranked results from the live web, with optional full-page fetch when a result needs it, not noisy crawl output.
Firecrawl runs a full web data API on one API key: Search, Scrape, Parse, Crawl, Map, and Interact. Search is where most agent workflows start. It queries the live web and returns ranked, LLM-ready passages you can hand straight to a model, no separate scrape step.
What comes back is current and citable: Firecrawl indexes news, finance, and government sources and tracks how often each changes, and two purpose-built indexes go deeper. The Developer Index covers 70M+ developer artifacts (READMEs, GitHub issues, PRs, and docs), refreshed daily, so a coding agent gets the exact PR that fixed a bug; the Research Index covers 3M+ arXiv papers with linked code, extended to 41M+ drug discovery, clinical, and biology papers via the Life Sciences category.
Both sit inside Firecrawl Alexandria, a library of 90+ data providers (official APIs like SEC EDGAR, FRED, and the World Bank, licensed publishers like Fiscal.ai and Particle, and Firecrawl's own indexes) that the same search call returns as ranked tools when you add alexandria to sources. Discovery is free; running a tool is billed at its listed price.
The catalogue itself is the argument for choosing Firecrawl here. It includes the Wayback Machine for how a page looked on any past date, Greenhouse job boards for every open role at a company, GitHub, Hugging Face, PyPI, and Stack Exchange for developer questions, Companies House and SEC EDGAR for registries and filings, and 80+ other providers, all reachable from the one search call an agent already makes.
A context parameter lets an agent state its intent instead of forcing it into keywords, and one endpoint reaches source types (web, news, images) and corpus categories (github, research, pdf) with time, country, and image-dimension filters.
It is also built to spend fewer tokens. Search returns query-relevant Highlights by default, roughly 10x fewer input tokens than full-page dumps, while scoring 94.7% on Firecrawl's SimpleQA evaluation, higher than any provider tested.
Independent testing agrees: on OpenBenchmarks' token-efficiency ranking for coding agents, Firecrawl is the most token efficient web search API on the search-only board, at a median of 7,456 task tokens. The question format on /scrape goes further, returning a grounded answer from a page for up to 100x fewer tokens and declining when the answer is not there.
Past search, /interact handles pagination, form fills, and post-click extraction in a session (natural language or Playwright), with profiles that keep login state across scrapes, and /search supports Zero Data Retention (enterprise: ["zdr"] end to end, or ["anon"] for Firecrawl's side) for compliance-sensitive work.
Try it in the playground, or via MCP, CLI, or the Python and Node SDKs. Free tier, no card.
Pricing: Paid plans start at $19/month billed monthly, or $16/month billed annually, for 5,000 credits, on top of a free tier of 1,000 credits a month. A search is 2 credits (one query returning up to 10 results), scraping is 1 credit per page, and PDF parsing is billed separately. You pay for the features you turn on and nothing else.
See how to build apps with Firecrawl agent and Claude Opus 4.6 for a full agent walkthrough.
Pros:
- Standalone search API with optional same-call extraction, so there is no second scraping layer to build
- Purpose-built Developer and Research indexes for code and academic work, plus
github/research/pdfcategories and source, time, country, and image-dimension filters - Token-efficient: Highlights on
/search(~10x fewer tokens, 94.7% on SimpleQA) and the/scrapequestion format (up to 100x) - One API for the whole loop: Parse for PDFs and documents inline,
/interactfor gated flows, natural-language schema extraction, and markdown tuned for RAG - Usage-based pricing with no per-seat surcharges, and Zero Data Retention available end to end
- Firecrawl keyless is a zero config web search API: no signup or API key, 1,000 free credits a month to evaluate before wiring anything up
Cons:
- Newer than the established SERP APIs, less brand familiarity for procurement. The core is open source on GitHub and the benchmarks are published, which gives procurement something concrete to evaluate in place of brand history
For deeper dives on the surrounding endpoints, see Firecrawl's search endpoint, scrape endpoint, and crawl endpoint.
The Neural Semantic Search Engine
Best for: AI agents requiring semantic discovery and research dataset curation when searching for AI research content
Exa is an AI-forward web search built around neural link prediction: it trains on how pages link to each other to model semantic relationships between them, rather than ranking by term frequency alone.
That approach can help on research-style queries where the useful sources are the ones other researchers cite. Ask for "breakthrough AI research" and Exa's neural search tends to surface papers that carry citation weight, though results quality depends on how well the query maps to Exa's index of academic and research content.
Exa's semantic search and data extraction features work well but need some setup compared to a straightforward search call.
Response times stay under a second on semantic queries, and real-time indexing pulls in fresh content within hours. Exa optimizes for source quality over breadth, so news, commercial, and other general-web sources are thinner than on broader indexes.
Pros:
- Neural link-prediction training gives semantic ranking that works well on research-heavy queries
- Response format is built for LLM consumption
- Source curation leans toward research and academic content
- Sub-second responses with fresh content indexed within hours
- Captures relationships between sources when the query maps to Exa's index
Cons:
- Exa generally requires more initial setup work than Firecrawl's simpler search API experience
- Smaller search index means less comprehensive coverage than APIs like Firecrawl
- Neural search effectiveness varies unpredictably across different domains and query types
- Limited traditional SERP features for teams expecting conventional search results
Check out our Exa alternatives guide and our detailed Firecrawl vs. Exa comparison to see how these platforms stack up.
AI Search and Research API
Best for: AI search and research workflows that need trustworthy source discovery with credibility assessment plus optional raw content inline
Tavily is an AI web searcher that leans on citation-ready sources meant to plug into LLM responses. It positions itself around source authority and citation metadata, aimed at RAG pipelines that need traceable references.
Their architecture centers on what they call "source-first discovery." A query for recent developments in gene editing returns peer-reviewed articles, news sources, and industry publications with summaries and citation metadata attached.
Tavily's platform spans /search, /extract, /crawl, /map, and /research endpoints. /search accepts include_raw_content to return raw HTML alongside ranked results in a single call, and /extract handles targeted content extraction when you already know the URLs to read.
Tavily offers 1,000 free searches monthly, then charges $0.008 per credit PAYG basic search on a pay-as-you-go basis with no volume minimums. The per-request pricing is transparent, though the lack of bundled monthly plans can make forecasting spend less predictable than tiered alternatives.
Pros:
- Source-credibility metadata attached to search results, useful when citations need to be traceable
- Response times in the 0.4-1.2 second range
- LangChain and LlamaIndex integrations with RAG workflow documentation
- Multi-endpoint platform (
/search,/extract,/crawl,/map,/research) covering search plus content workflows
Cons:
- Semantic search style is different from neural search engines like Exa; teams heavily reliant on embeddings-based matching may prefer a dedicated semantic layer
- Response format optimized for citations rather than deep structured extraction across many pages
Check out our Tavily alternatives guide and our detailed Firecrawl vs. Tavily comparison.
Parallel AI
Agentic Web Research at Scale
Best for: Research-heavy agents that need high-accuracy outputs with clear sourcing, particularly for enterprise or compliance-sensitive workflows
Parallel AI (officially Parallel Web Systems) is a newer entrant building web infrastructure specifically for AI agents. It raised a $100M Series A in early 2025 with the thesis that existing search infrastructure wasn't built for AI as a first-class user.
The core differentiator is accuracy. Parallel benchmarks itself at 47% on the HLE (Humanity's Last Exam) benchmark, compared to Exa at 24%, Tavily at 21%, and Perplexity at 30%. Every result includes provenance and evidence, not raw links or ranked snippets.
Its product suite covers four main use cases:
- Search API: Real-time web queries optimized for agent consumption with sourced, evidence-backed results
- Task API (Deep Research): Multi-step research that reasons across sources rather than just returning links
- Find All: Dataset building at scale for teams that need comprehensive domain coverage
- Web Enrichment and Monitor API: Enrich records with live web data and track changes over time
Pros:
- Evidence-backed results with full provenance on every output
- 47% HLE benchmark accuracy, ahead of Exa (24%), Tavily (21%), and Perplexity (30%)
- Pay-per-query pricing (not per token) for predictable cost scaling
- Multi-step research via Task API for complex agent workflows
- SOC 2 Type II certified
Cons:
- Newer platform: ecosystem integrations, SDKs, and community resources still maturing
- No public pricing listed
- No free tier for testing before committing
- Less proven in production at scale compared to more established alternatives
Traditional Web Search APIs
The Google-Powered SERP Specialist
Best for: Applications requiring comprehensive Google search coverage with reliable data extraction
ScrapingDog operates as a specialized intermediary between your application and Google's search results. Rather than building their own search index or developing AI-native capabilities, they focus entirely on one thing: reliably extracting Google's SERP data and delivering it in clean, structured JSON format. You get access to Google's massive search coverage, rich result types, and familiar ranking algorithms without dealing with proxy rotation, rate limiting, or HTML parsing complexities.
Their Google Search API handles the full spectrum of SERP features including organic results, People Also Ask sections, featured snippets, local results, and shopping data.
What sets ScrapingDog apart is their infrastructure focus, rather than algorithm or AI innovation. That means it doesn't have capabilities like semantic search or LLM-optimized outputs. You'll need developers to build additional processing layers for modern AI workflows.
Pros:
- Google search coverage with advanced search parameter support like complex operators and filters
- Competitive pricing from $0.29 to $1.00 per 1,000 searches with generous free tier
- Proven infrastructure handling 400+ million monthly requests
Cons:
- No AI-native capabilities or semantic understanding beyond Google's algorithm
- Only JSON output (requires additional processing)
- Complete dependency on Google's search results (and its terms and conditions) without independent relevance improvements
- Limited to SERP data extraction without full content scraping like other web search API offerings
The Multi-Engine Enterprise Solution
Best for: Large organizations requiring maximum reliability and comprehensive search engine coverage across multiple platforms
SerpAPI operates as the wrapper service for search engine data, providing unified access to over 40 different search engines and platforms through a single integration. Rather than building separate connections to Google, Bing, Yahoo, DuckDuckGo, Baidu, Yandex, Amazon, Yelp, and dozens of other services, developers can access all of them through SerpAPI's standardized JSON interface.
However, SerpAPI's scope doesn't cover the full needs for modern AI applications. The service returns only search result metadata including titles, snippets, and links rather than full page content. If you need content for LLM processing, you'll have to build additional infrastructure to fetch URLs, convert HTML to text, and handle content extraction separately.
SerpAPI is also very expensive compared to all the alternatives. Combined with premium pricing starting at $75 monthly for 5,000 searches and scaling to $275 for 30,000 searches, the service targets enterprise customers who value reliability guarantees, multi-engine flexibility, and premium cost customer support.
Pros:
- Enterprise-grade reliability with 99.9% uptime SLA and verified real-time data delivery
- High-performance architecture supporting up to 100 requests per second with global infrastructure
- Exceptional customer support with responsive technical assistance through in-product chat
Cons:
- Premium pricing that's 10-50x more expensive than focused search API alternatives
- Requires additional development to build content extraction pipeline for LLM workflows
- Multi-engine complexity may be overkill for applications needing only basic Google search
- Limited to predefined SERP formats rather than comprehensive web data extraction capabilities
The Affordable SERP Middle Ground
Best for: Developers seeking cost-effective Google search access without enterprise complexity
Serper positions itself between budget and premium SERP API options, offering straightforward Google search results through a clean REST API. Rather than competing on advanced features or multi-engine support, they focus on delivering reliable Google search data at volume-friendly pricing that scales with usage. The service targets developers who need more than basic SERP scraping but don't require the larger feature sets of enterprise tools.
Serper emphasizes partnerships and framework integrations over direct developer outreach. For example, their documentation appears less accessible than some competitors (serper.dev/docs doesn't exist). Serper has lots of AI integrations, such as LangChain, so you might have an easier time accessing it through those partner tools.
Pros:
- Volume-friendly pricing scaling from $1.00 to $0.30 per 1,000 searches for large users
- Simple API structure with clean REST endpoints and standard search parameters
- Google search results with familiar SERP data including organic results and metadata
- Focus on reliability over feature complexity appeals to straightforward use cases
Cons:
- No free tier for testing compared to generous trial offers from competitors
- Limited publicly accessible documentation creates integration uncertainty
- Fewer advanced features compared to comprehensive platforms like SerpAPI
- Google dependency creates potential service disruptions if Google's policies change
The Privacy-Focused Alternative
Best for: Research applications, business intelligence monitoring
Brave Search API runs on an independent search index that doesn't rely on Google's infrastructure or tracking systems. The company, known and loved for their commitment to user privacy, built their own web crawler and search algorithms to give developers access to search results without the use of surveillance-based business models. Brave Search doesn't collect data during API usage, so it can be useful for healthcare applications, financial research, government projects, or any scenario where query confidentiality is important.
Brave does have some notable limitations, however. It has a smaller search index than Google or others, which means less comprehensive results for niche topics or very recent content. Unlike AI-native platforms like Exa or Firecrawl, Brave Search focuses on traditional keyword-based search without semantic understanding or LLM-optimized outputs.
See Firecrawl vs Brave Search API for a direct feature and use-case comparison.
Pros:
- No user tracking or data collection during API usage
- Independent search index free from Google dependency
- $5 per 1,000 queries pricing for AI applications
Cons:
- Removed free tier - Brave Search API no longer offers a free plan, making it harder to test before committing
- Smaller search index means less coverage than Google-powered APIs
- Limited relevance for niche topics or very recent content
- Rate limits may be restrictive for high-volume applications (1 req/sec baseline)
How do you choose a web search API?
Consider the following criteria when choosing your web search API:
Search approach and data quality: The web search API should align with your application's needs. Traditional SERP APIs tend to deliver Google's familiar ranking algorithms, which is good for applications requiring specific SERP features like Knowledge Graph data. AI-native search APIs excel at semantic understanding or research discovery but may have smaller indices or different relevance models than users expect from Google-powered results.
Integration complexity: APIs with strong LangChain support reduce implementation complexity for AI developers, so teams can prototype faster and switch between search providers without rewriting all of their integration code. Conversely, platforms requiring custom infrastructure or complicated authentication can slow teams down. See our guide to building web scraping agents with LangGraph and Firecrawl for a practical example.
Vendor lock-in risks: Independent search APIs provide protection against sudden platform changes or forced migrations to pricey and bloated enterprise ecosystems. When choosing a tool, check whether it could restrict access, change pricing models, or force you into using specific platforms in the future.
Content extraction capabilities: Some APIs return only search metadata, while integrated platforms combine search discovery with content extraction get rid of this complexity. Consider the needs of your entire workflow rather than just the search functionality component.
Data for AI agents: If you're building autonomous agents, search is only part of the picture. Your API needs to feed agents with data they can act on - not just links and snippets. Look for platforms that support agentic workflows end-to-end: autonomous browsing for multi-step tasks, parallel processing across sources, and clean structured output that agents can reason over without additional preprocessing. An API that works well for a simple RAG pipeline may become a bottleneck when your agent needs to navigate, extract, and synthesize across dozens of pages in a single task. Check, too, whether it can reach sources that never appear as web pages, such as filings APIs, economic data, and licensed publisher feeds, without a separate integration for each one.
Takeaways
When it comes to web search APIs, integrated platforms have clear advantages over traditional search-then-scrape approaches, and AI-native platforms are increasingly outpacing traditional SERP APIs for modern development workflows.
Choose platforms that align with where AI development is going rather than trying to adapt legacy search approaches to modern requirements. If you're building AI agents or RAG systems, you have to be even choosier with your search API.
Firecrawl returns fresh, clean, ranked results from the live web, not whatever a crawler grabbed, with optional full-page fetch when a result needs it. Teams that were running a SERP API, a separate scraper, and a PDF parser replace all three with one API. Its combination of Search, Scrape, Parse, Interact, and an autonomous /agent endpoint covers the full Find → Extract → Clean → Use workflow, at pricing that typically beats assembling the same stack from separate services.
Open-source agent runtimes like Hermes already ship Firecrawl as their default web backend, routing both web_search and web_extract calls through it automatically.
Traditional SERP APIs remain viable for specific scenarios but require additional development overhead that AI-focused platforms take care of by default. The cost savings of metadata-only APIs disappear when factoring in the infrastructure needed for content extraction that AI workflows typically require (and in the case of SerpAPI, you're already paying premium prices just to search!).
The future of infrastructure is AI-first, and your web search partner should be too.
Sign up for Firecrawl and start searching the web for free.
Frequently Asked Questions
What's the difference between SERP APIs and Search APIs?
SERP APIs specifically scrape and reformat data from existing search engines like Google or Bing - they act as middleman services that parse SERPs and return structured JSON. Search APIs is the broader category that includes both SERP scrapers and independent search engines. Firecrawl goes beyond both: it searches across the live web (news, research, finance, government) with freshness monitoring, returns ranked results with query-relevant excerpts by default and can attach full content extraction in the same call when needed, and supports autonomous multi-step research via the /agent endpoint - all in one platform. Other examples include Exa's neural semantic search and Brave's privacy-focused independent index. All SERP APIs are Search APIs, but not all Search APIs are SERP APIs.
How do AI-native search APIs work differently from traditional search?
Traditional search APIs match keywords and return results based on text similarity and popularity signals. AI-native search APIs like Exa and Tavily use neural networks to understand semantic meaning and context - they can find relevant information even when it doesn't contain your exact search terms, and they format results specifically for AI consumption rather than human browsing.
What happened to Bing Search APIs in 2025?
Microsoft shut down Bing Search APIs on August 11, 2025, pushing users toward their Azure AI Agents platform with 'Grounding with Bing Search.' Developers should consider independent search providers that aren't subject to sudden platform changes from major tech companies.
Do web search APIs return full page content or just snippets?
It depends on the provider. Traditional SERP APIs (SerpAPI, Serper, ScrapingDog) return only search metadata - titles, URLs, and short snippets of 150-300 characters. AI-native platforms like Firecrawl return titles, URLs, and query-relevant markdown excerpts by default, which answers most queries directly, and can attach full page content in the same call when a result needs it, so you fetch pages only when the excerpt is not enough.
How much do web search APIs actually cost in production?
The advertised per-query price is rarely the full picture. Factor in: token processing fees, volume tiers, premium features billed separately (PDF parsing), and rate limit overages. Firecrawl's search costs 2 credits per 10 results. Tavily charges $0.008 per credit PAYG basic search. SerpAPI starts at $75/month for 5,000 searches - 10–50x more expensive than alternatives at comparable volume. Always prototype with free tiers and run cost projections before committing.
Which web search API is best for RAG systems and LLM grounding?
Firecrawl is a strong choice for RAG: it returns fresh, ranked results with query-relevant excerpts from the live web, so the context going into your pipeline is signal-rich rather than noisy crawl output, and it can attach full page markdown in the same request when a result needs it, with no extra scraping step. It also has native LangChain and LlamaIndex integrations. Exa is a strong alternative for semantic search that surfaces conceptually relevant sources; Tavily for citation-ready structured output with source credibility scoring. Firecrawl is also a strong choice for autonomous search: its /agent endpoint handles multi-step research tasks in parallel, making it ideal for agentic RAG pipelines.
How do I integrate a web search API with LangChain or other AI frameworks?
Most modern web search APIs provide native integrations with LangChain, LlamaIndex, and MCP (Model Context Protocol) servers. Firecrawl, Exa, Tavily, SerpAPI, and Serper all have official LangChain tools you can import directly. For MCP-based agentic workflows, look for providers that expose MCP server support. Check whether packages are officially maintained by the provider - these are far less likely to break when frameworks update.
Are there web search APIs with strong privacy guarantees?
Brave Search API is the standout option for privacy-sensitive use cases - it runs on an independent index and doesn't collect or log API query data, making it suitable for healthcare, legal, and financial applications. Note that Brave recently removed its free tier, so you'll need a paid plan to get started. For GDPR-compliant deployments, verify any provider has a Data Processing Agreement (DPA) available. Most AI-native APIs (Firecrawl, Exa, Tavily) don't sell query data, but review privacy policies carefully if regulatory compliance is a hard requirement.
Which web search API is most token efficient for AI agents?
Firecrawl is built for token efficiency across the stack. Its default search response returns ranked, LLM-ready passages via query-relevant Highlights instead of full pages, which cuts input tokens by roughly 10x compared to processing entire result pages while topping SimpleQA at 94.7%. On top of that, the /scrape endpoint now supports a question format (type: question) that takes a URL plus a query and returns just the grounded answer, up to a 100x token reduction versus fetching and chunking the whole page. If the answer isn't on the page, the model declines rather than fabricating one. Together, that means fewer tokens per answer, less context-window pressure on the model, and lower spend across a multi-step agent loop.
Which web search API returns data providers as tools in the search response?
Firecrawl, through Firecrawl Alexandria. Add alexandria to the sources parameter and the response carries a tools array next to the web results, drawn from official APIs such as SEC EDGAR and FRED, licensed publishers such as Fiscal.ai, Benzinga, and Particle, and Firecrawl's Research, Developer, and Government indexes. Exa, Tavily, Parallel, SerpAPI, ScrapingDog, Serper, and Brave return pages, snippets, or SERP data.
How much does Firecrawl Alexandria cost?
Finding tools is free on any search. Running a tool goes through the scrape endpoint with an alexandria block (provider, capability, options) in place of a URL and is billed at the price listed on the tool, which is deducted from your Firecrawl credits. Prices vary by provider, so read the contract before wiring a tool into a loop. Firecrawl Alexandria needs an API key on a team where it is enabled, and some licensed publishers require an organization admin to accept their terms once before the first call.