We raised a $75M Series B led by Smash Capital, with participation by Altos Ventures, Nexus Venture Partners, Y Combinator, Freestyle, and Offline Ventures.
We’re going to spend a good chunk of it buying knowledge from people, which takes some explaining.
Today we’re introducing Alexandria. It brings official data providers, custom connectors and Firecrawl’s own indexes together with the live web, so your AI agent has one way to find a source, see what it holds and pull from it.
We named it after the ancient Library of Alexandria. If you wanted the world’s knowledge in one place back then, you physically moved it there and hoped nothing happened to the roof. Papyrus doesn’t copy itself.
Today, we can share information without shipping scrolls around, but much of what people know is still out of reach. Someone might spend a lifetime learning something useful without ever writing it down. A publisher might maintain a valuable dataset that your AI agent has no way to access.
We want to make that knowledge available and give the people who contribute it a reason to keep doing so. That means paying them when AI agents use it.
We already do this through agreements with several data providers, including Wikimedia Enterprise. This funding will help us bring that opportunity to more people and organizations, while improving search and expanding the sources AI agents can reach through Alexandria.
That’s how we want to build the library for superintelligence, with the knowledge people have today and the discoveries humans and AI agents make next.
We started with a problem of our own
Before Firecrawl, we built Mendable, an AI chat product for documentation. Mendable worked. What we learned building it was that getting clean, reliable information out of the web was the hardest part of the whole stack, and that other teams building with AI were solving the same problem from scratch.
So we built Firecrawl to handle that work. Give it a URL and it handles everything from crawling and rendering to parsing and cleanup.
We figured a few hundred people had that problem. Over 1.5 million users build with Firecrawl now.
Solve one problem well and you get promoted to the next one, whether you wanted it or not. As our users’ AI agents got more capable, they needed broader coverage, better search and sources that search and scraping alone couldn’t reach.
An AI agent researching a company might start with its website, then need financial data and filings to understand the business. Each source adds useful context, and each comes with its own API, pricing and data formats. Maintaining those integrations takes time away from building.
Leaving a source out can affect the answer. Even the strongest model can’t reason over information it never found.
Before you order the hoodies
So you're building an AI customer-support tool. You've bought the domain. This is the point at which things become, technically, real.
Before you spend six months on it, there's a question worth asking, and it's a slightly uncomfortable one: who else already had this idea?
The answer is never "nobody." The answer is also never the three names you can think of off the top of your head. What you actually want to know is which startups are working on this, who they sell to, and whether the thing you think makes you different is already the headline on somebody else's homepage. (It might be. It usually is. Better to find out now.)
This is the kind of research that sounds easy and isn't, because the information is scattered across a bunch of directories and websites that were each built for humans clicking around, not for an agent doing it in bulk. With Alexandria, your agent can query those directories directly and walk through whole startup batches at once. It can compare what each company actually builds and pull the underlying records, which is how you separate the real competitors from the companies that merely put "AI" in their description because it was 2024 and everyone did.
Okay. Say you've done that, and you still want to build it. Good. There's one more small detail: somebody has to pay you.
Same agent, same connection. Have it look for companies that match your target customer, then use people enrichment to find the actual humans you'd want to talk to. For support software, that's probably whoever runs customer support. The point is you go from "who am I competing with" to "who might buy this" without rewiring your agent to a new data source every time the question changes. That part is boring. It's also the part that usually eats the week.
None of this gets you out of building something people want. It just means you'll know who else is building it, and who might want it, before you order the hoodies.
More places to look
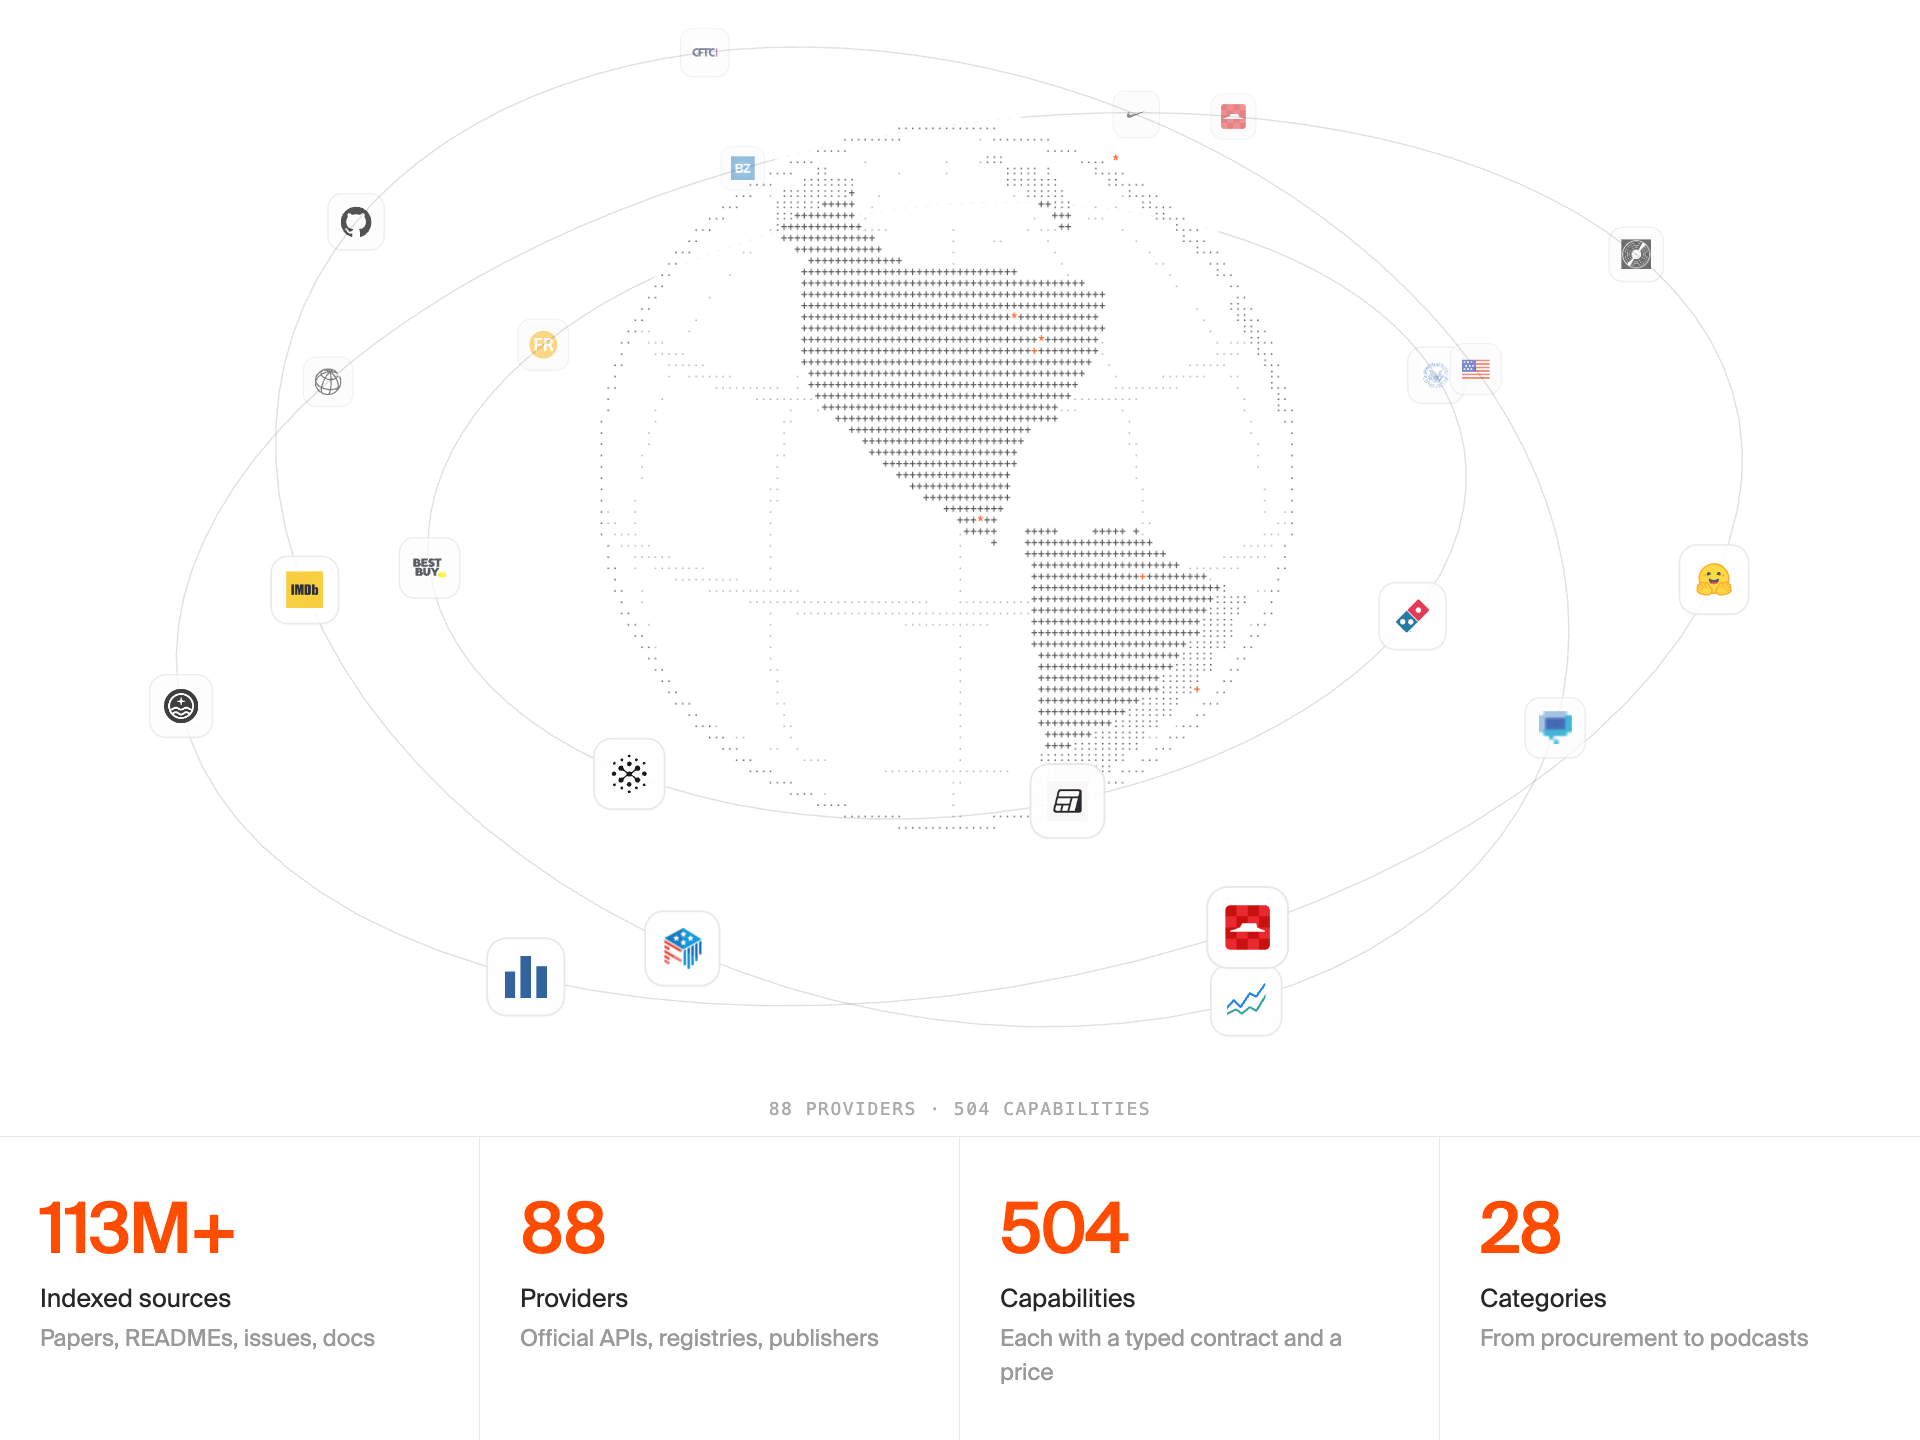
Alexandria gives AI agents a common way to discover sources, understand what they provide, and retrieve information through the Firecrawl API you already use.
Those sources include the live web, official data providers and Firecrawl's own indexes, alongside custom connectors and workflows. An AI agent can read a webpage or search an index, query a provider or use specialized tools to collect entire datasets.
Our Research Index includes tens of millions of scientific paper abstracts. Our Developer Index spans tens of millions of primary sources across documentation and READMEs, issues and merged pull requests. Our Government Index covers laws, regulations, and ordinances.
Across the verticals we tested, AI agents using Alexandria scored 21% higher on answer quality than those using built-in web tools. We used the same model and prompts across 845 tasks, with blind AI judging.
Making knowledge worth sharing
We already pay official data providers through individual agreements, most notably Wikimedia Enterprise. Millions of requests for Wikipedia data flow through Firecrawl each month. We pay for direct access to that data, supporting Wikipedia while giving our users a better way to retrieve it.
We’re using this funding to help individuals, content creators and organizations earn from what they know through a self-service system we plan to open soon. That includes people whose expertise has never been shared online, and eventually could include AI agents making useful discoveries of their own.
What we’re building next
We’ll keep investing in search and Alexandria by improving access to the live web, building deeper indexes and retrieval systems and connecting more first-party sources.
To everyone who found Firecrawl early, filed an issue or trusted us in production, thank you. Your feedback showed us what to build next.
Alexandria starts today. Give it a company to research, scientific work to compare or a technical question to investigate. Use it on its own or alongside web search and scraping to give your AI better source material.
Connect your AI agent through Firecrawl’s MCP or build with the API.
For the CLI and skills, ask your AI agent to run this command.
npx -y firecrawl-cli@latest init --all --browserThen restart your AI agent to load the skills.
If you create content, maintain data or have expertise that AI agents should be able to use, we’d like to hear from you.
We’re building Alexandria so AI agents can find and build on what we know today and what we discover tomorrow, while the people who contribute that knowledge share in the value it creates.